
Own product · Open science
Pipette.
Every morning Pipette reads every new paper on arXiv, bioRxiv, medRxiv and 58 leading journals, and publishes a short edition of the ones worth knowing about. It never rewrites science: for each paper it quotes the sentence of the abstract that states the main result. Free, no ads, no accounts, and open source.
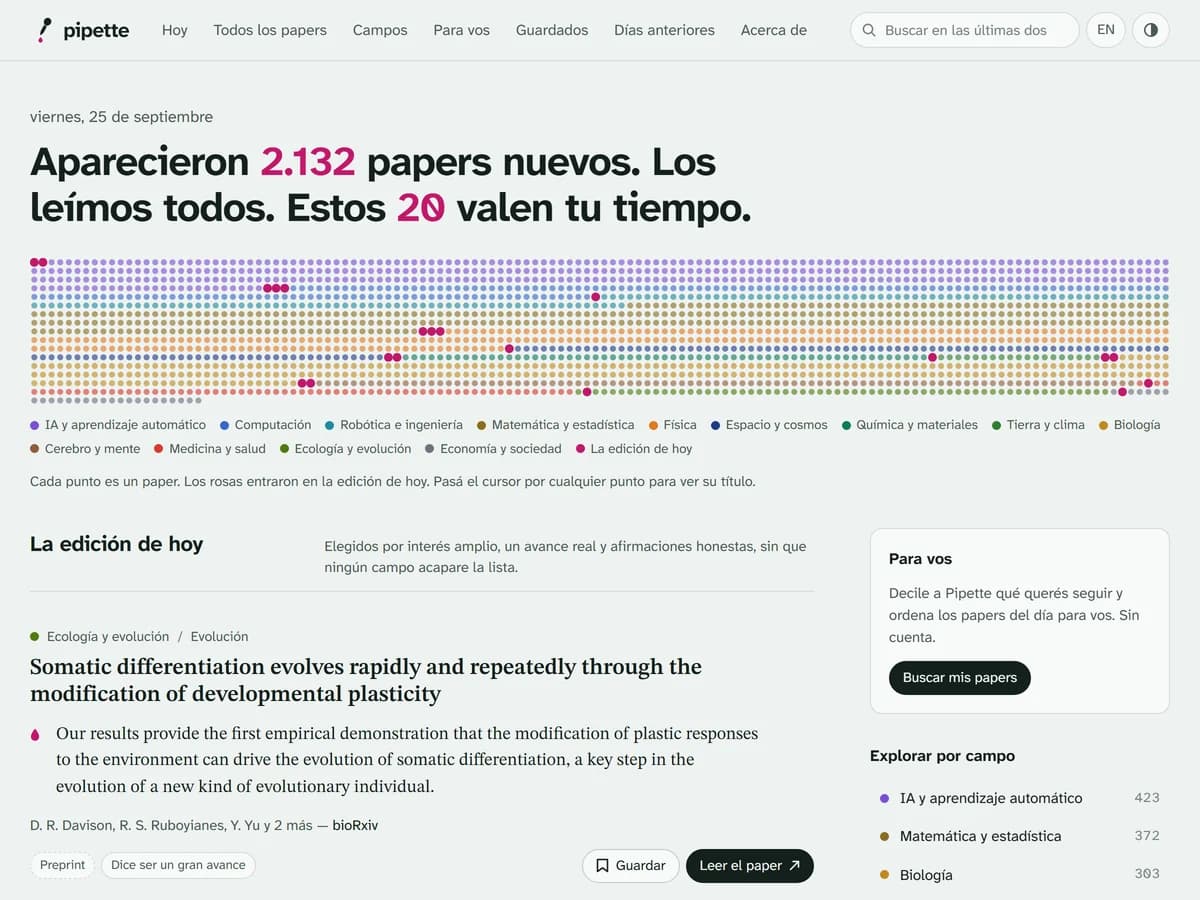
Thousands of new papers appear every day, and AI is about to multiply that number. Existing tools either search for something specific or summarize with AI, putting words in scientists' mouths.
Finding what matters each day without reading two thousand abstracts, without one field drowning out the rest, and without a machine inventing what a paper says.
We use Jev, a decision model that cannot generate text: it only chooses among options and reports calibrated probabilities. It answers ten questions about every paper, a public formula picks the edition, and readers always see the authors' words.
A daily Python AWS Lambda reads arXiv, bioRxiv, medRxiv and OpenAlex, asks Jev and publishes open JSON to S3. The site is Next.js on Vercel, in English and Spanish, with field and topic pages, sitemaps listing every paper, structured data and IndexNow pings.
About two thousand papers read every weekday, for roughly 17 US cents of model usage. The data is published under CC0 and the code is open on GitHub.
In production since September 2026, updated automatically every morning.
None: it is Ferced's own product, built and kept free for everyone who reads science.
Medium: ranking science from every field with honest criteria, in two languages and without generating text, needed clear editorial rules as much as code.